Blog Post
MTBF vs. MTTR: What's the Difference and Why It Matters
Understand the key differences between MTBF and MTTR, how they impact equipment availability, and actionable strategies to improve reliability and maintainability.


Key Takeaways
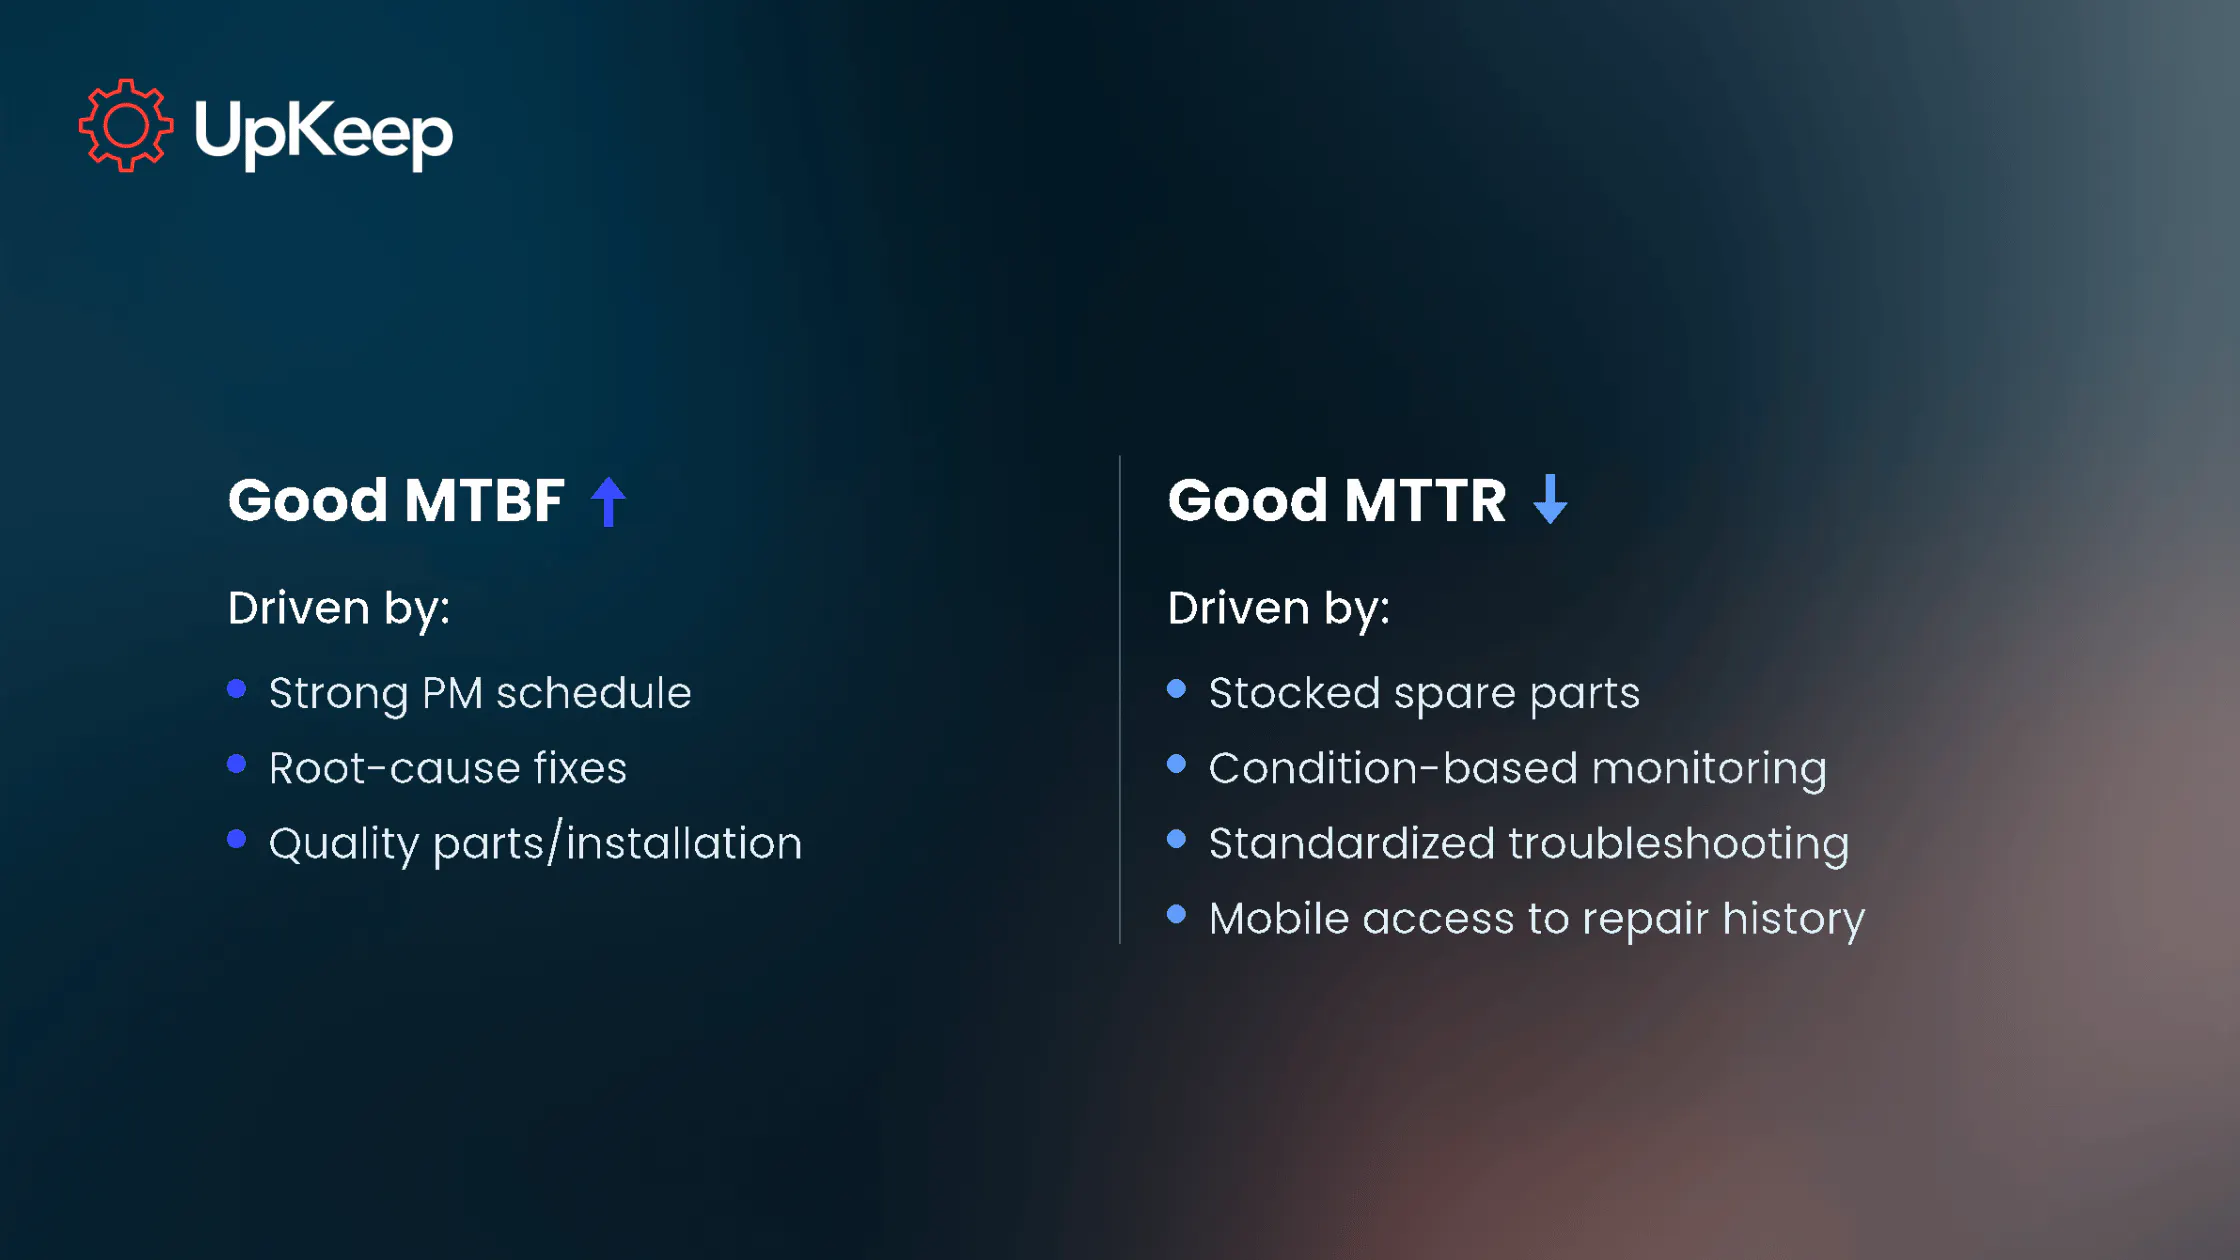
MTBF measures reliability: the average operating time between failures.
MTTR measures maintainability: how long it takes to restore a failed asset.
Both metrics depend on accurate operating time and repair time data, which is why the underlying tracking matters as much as the calculation.
Together, MTBF and MTTR determine equipment availability, and that number feeds directly into overall equipment effectiveness.
Two acronyms show up constantly in maintenance conversations: mean time between failure (MTBF) and mean time to repair (MTTR). They're often mentioned in the same breath, but each one measures something different. The first tells you how reliable your equipment is, while the second tells you how quickly your team gets it back online after something breaks.
Although often used together, mixing up MTTR and MTBF can lead to significant problems. A team that's tracking the wrong metric (or the right metric with the wrong inputs) can end up making decisions based on numbers that don't reflect what's actually happening on the floor. But when they’re calculated and analyzed correctly, they work together to tell a more complete story about asset performance.
What Do MTBF and MTTR Measure?
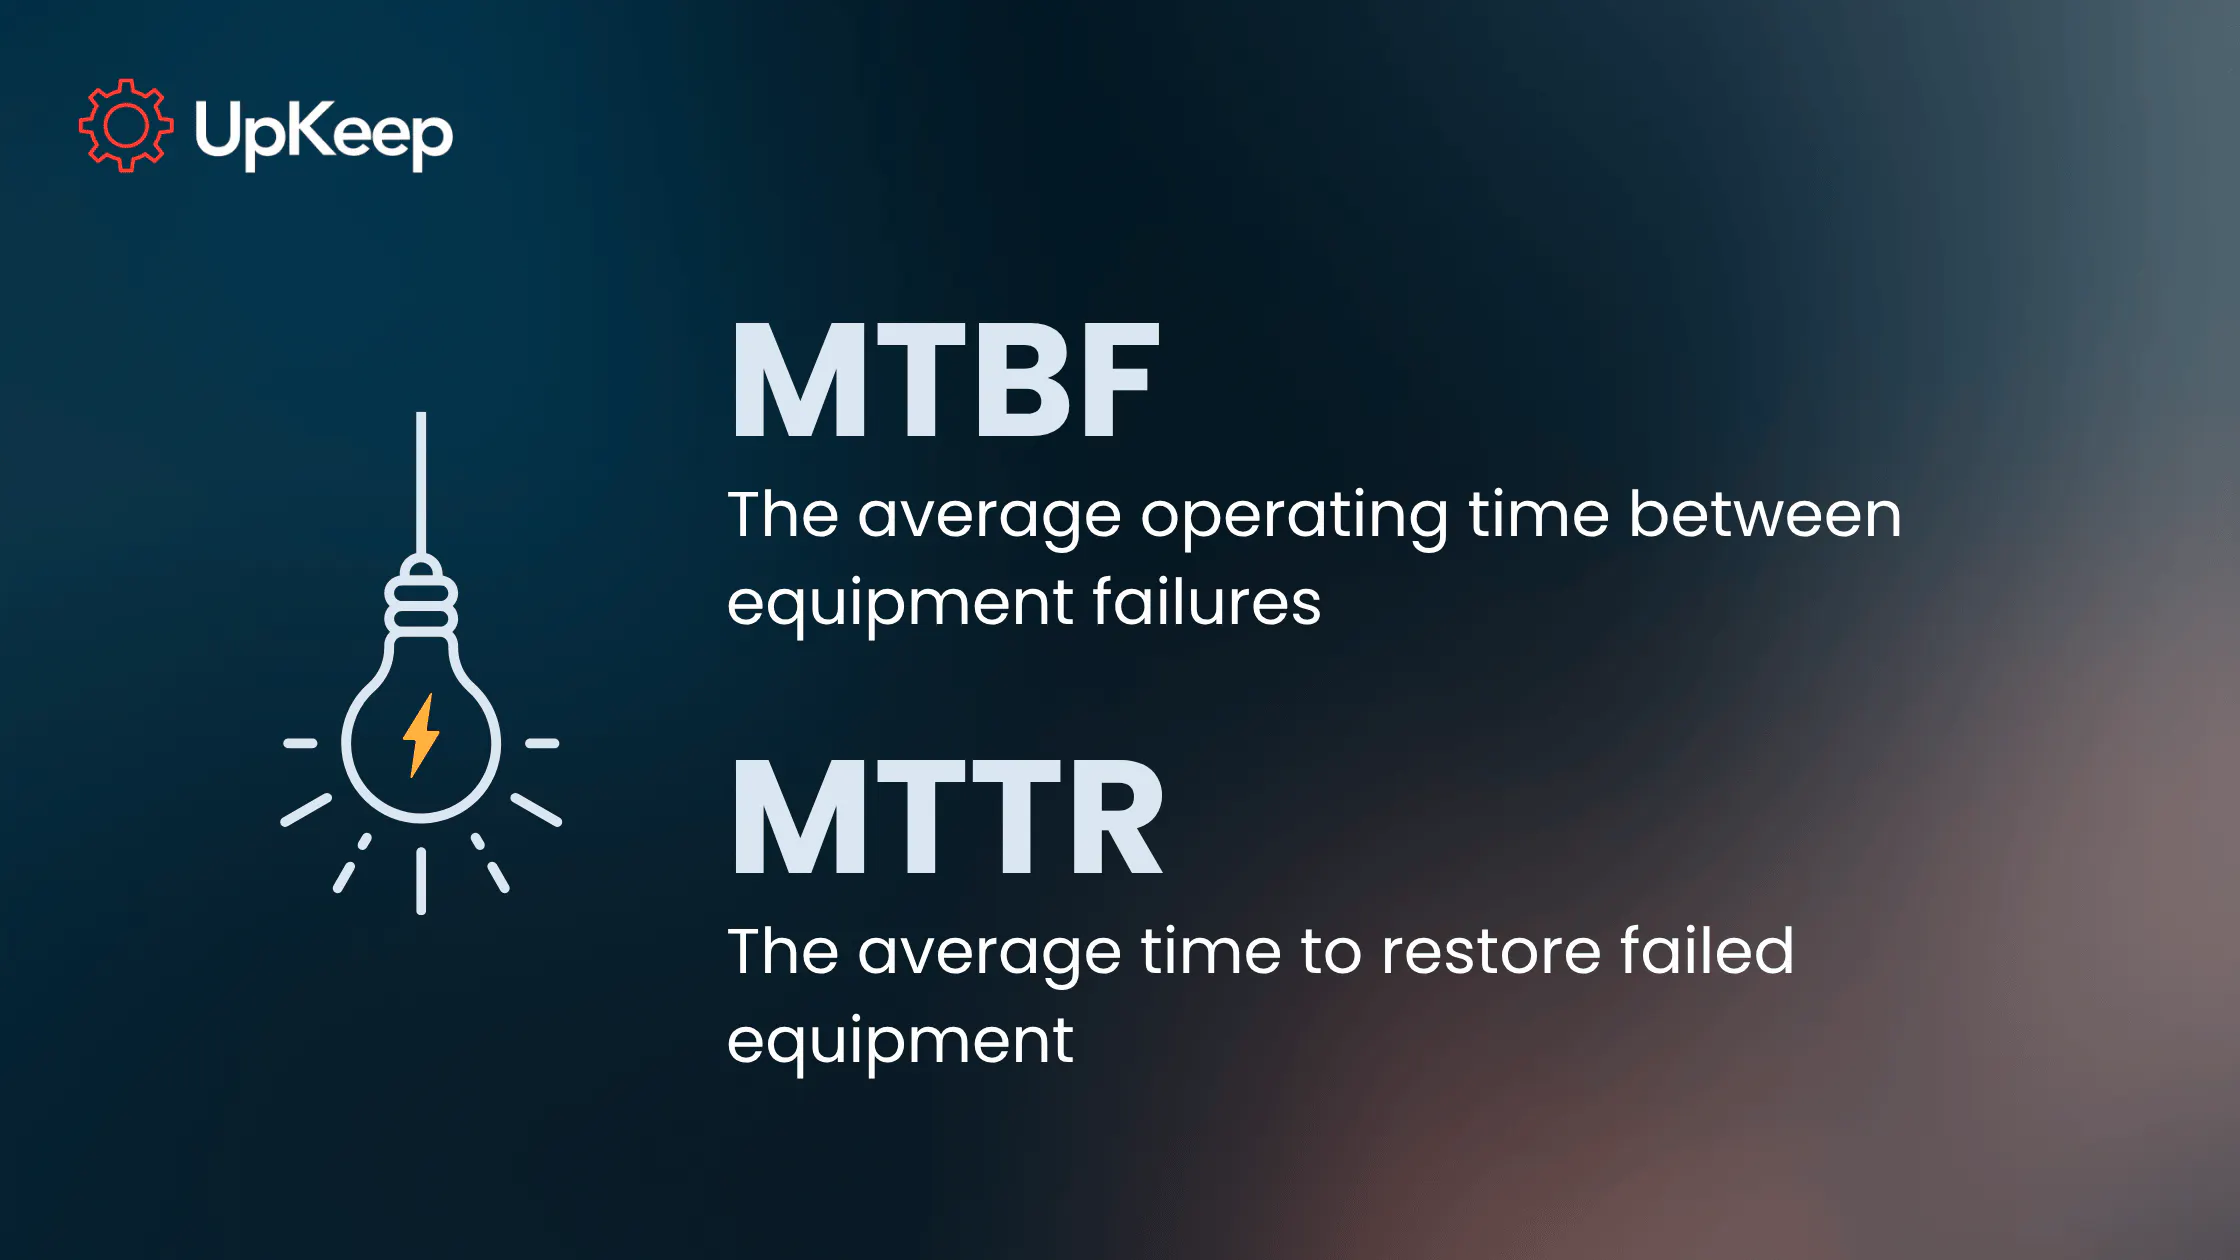
MTBF is the average operating time between failures for repairable equipment, whereas MTTR is the average time it takes to restore a failed asset to working condition once it fails. To put it simply, MTBF measures reliability, and MTTR measures maintainability.


A good MTBF depends on the equipment involved. High-reliability components like SSDs can run around two million hours between failures, while servers typically land closer to 15,000 hours, according to Atlassian, so benchmarks only hold up when you're comparing equipment in the same category.
In contrast, a good MTTR is a low number, indicating an efficient process. A high MTTR points to friction somewhere in that process, like a slow response time, a missing part, or an unclear diagnosis path.
Instantly capturing operating hours and repair time through automated work orders, like on UpKeep’s CMMS, helps keep both numbers trustworthy.
An important detail that commonly trips teams up is what actually counts toward MTBF. The metric only accounts for time the asset was actually running; it doesn't factor in scheduled downtime like changeovers or planned maintenance. That's an important distinction, because comparing MTBF across two assets with very different maintenance schedules can be misleading even when they're the same type of equipment.
MTBF vs. MTTR: Key Differences
MTBF and MTTR answer different questions, pull from different data, and point maintenance teams toward different fixes. Here's how they break down side by side:
What they measure: MTBF measures how often equipment fails. MTTR measures how fast a team gets it running again once it does.
Direction of "good": You want a higher MTBF but a lower MTTR.
Data inputs: MTBF relies on operating time and failure counts. MTTR’s inputs are repair time and repair counts. Mixing those inputs skews both numbers.
The operational question each answers: A team with a reliability problem needs to look at MTBF. A team with a repair-speed problem needs to look at MTTR. The fix for each looks completely different.
Because these metrics point to different root causes, tracking them is crucial. UpKeep's reporting can break down both metrics by individual asset so a manager can quickly see whether a specific machine has a reliability problem, a repair-speed problem, or both.
MTBF Formula and How to Calculate It
MTBF is found by dividing the total operating time by the number of failures during that period.
MTBF = Total operating time / # of failures in that time
Remember, only the actual running time counts toward the total, because repair time and planned maintenance don't belong in the numerator. Using calendar time instead of actual operating time inflates MTBF and makes equipment look more reliable than it actually is. To avoid that error, track operating hours and failures automatically at the asset level rather than reconstructing run time from logs after the fact.
What Does the "R" in MTTR Stand for?
MTTR looks like a single, well-defined metric, but the "R" isn't as fixed as it seems. Depending on who's using the term, it can stand for repair, recovery, respond, or resolve, and each version measures a different part of an incident.
The basic formula stays the same regardless of which definition is in play:
MTTR = Total repair time / Number of repairs
What changes is where the clock starts and stops. Here's how the four meanings typically break down:
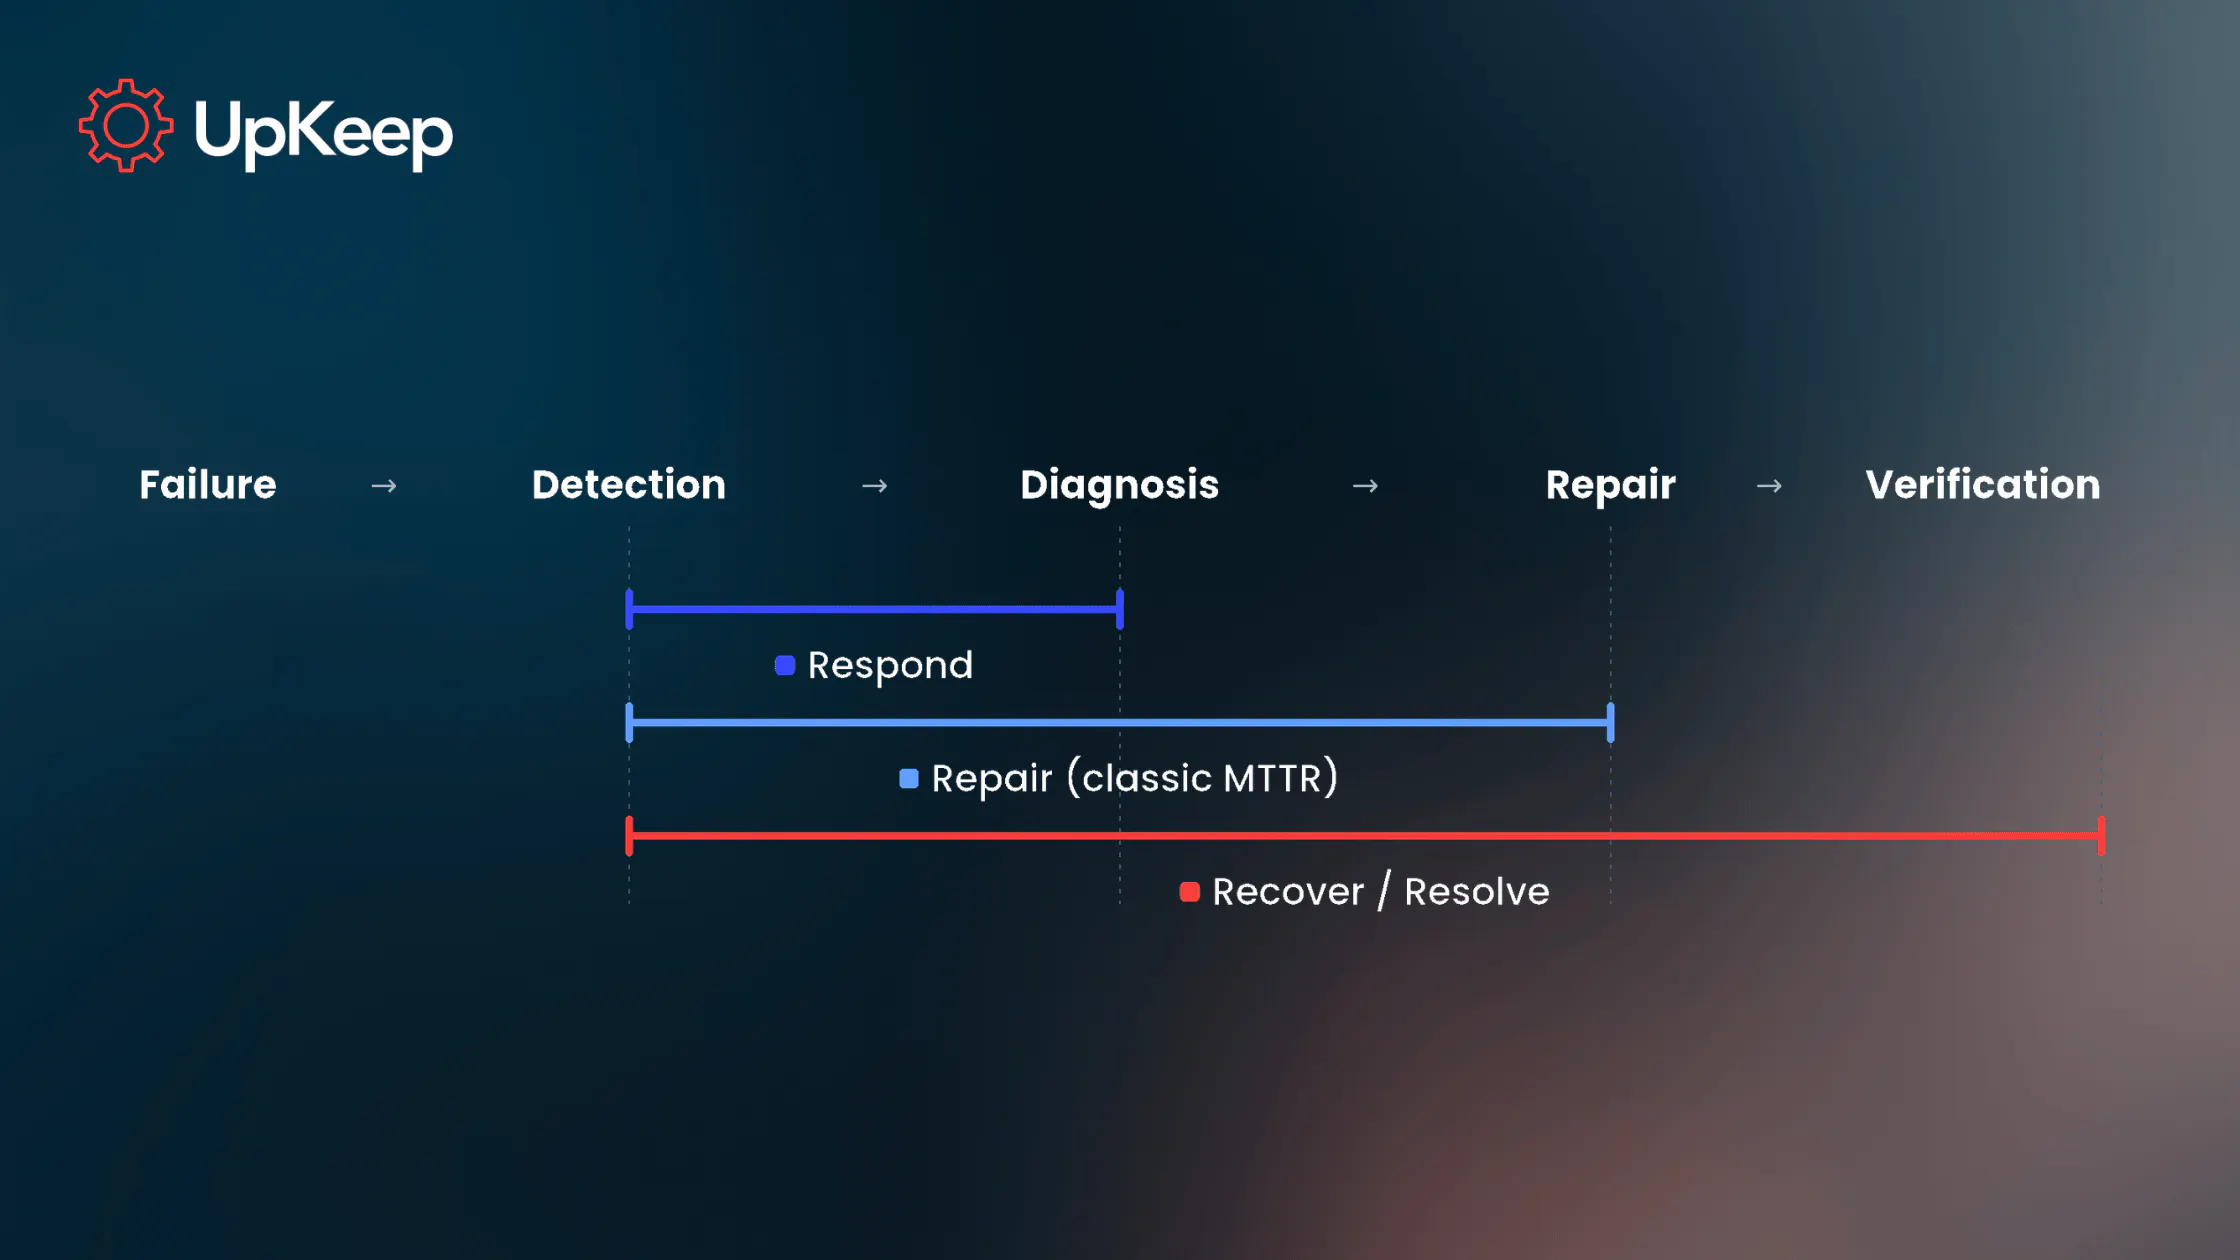
Mean time to repair: The classic definition. It tracks from failure through detection, diagnosis, and the fix and also accounts for the lead time it takes to get the right parts.
Mean time to respond: Measures how long it takes a team to react once an issue is flagged, not how long the fix itself takes.
Mean time to recover or resolve: The broadest version. It covers everything from detection to diagnosis, full restoration, testing, and confirmation that the issue is truly resolved.
Each "R" maps to a different point in the work order life cycle: when the failure happened, when a technician started work, and when the asset was verified back in service. Which of those timestamps a team captures determines whether they're measuring repair, response, or full recovery.

Teams comparing MTTR across sites or against a vendor benchmark need to agree on which definition they're using first, or else the comparison won't mean anything. A technician who starts the timer at "wrench-on" reports a very different number than one who starts it at "ticket created," even for the exact same incident. Maintenance teams juggling SLAs with equipment vendors or internal uptime targets need everyone using the same clock.
How Do MTBF and MTTR Work Together?
MTBF and MTTR combine to determine equipment availability, calculated as MTBF divided by the sum of MTBF and MTTR.
Availability = MTBF / (MTBF + MTTR)
Availability calculated this way feeds directly into overall equipment effectiveness (OEE), the standard measure of how productively equipment is used on a production floor.
A team can raise availability either by extending MTBF so equipment fails less often or shortening MTTR so repairs happen faster. To put those solutions into practice, track operating time and repair time at the asset level so availability can be calculated automatically instead of rebuilt in a spreadsheet each month.
The formula shows that availability isn't a single lever, and neither approach to raising it is inherently better than the other. The right path depends on what's driving downtime for a given asset, which is why segmenting MTBF and MTTR by asset is more useful than tracking one blended number.
UpKeep can calculate availability automatically from logged operating and repair time so a manager gets the number without building a separate spreadsheet formula every month.
Common Mistakes to Avoid When Tracking MTBF and MTTR
As you track MTBF and MTTR, watch out for a few recurring errors:
Using calendar time instead of actual operating time: This is the most frequent error, and it inflates MTBF enough to make a declining asset look stable. It shows up often in default CMMS report templates that don't flag the assumption.
Counting scheduled PM as a failure: This artificially deflates MTBF, which can make a reliable asset look like it needs replacing when it doesn't.
Relying on active repair time only: Not accounting for total downtime, including time spent waiting on parts or a technician, makes a team's MTTR numbers look better than they actually are and hard to compare against peers measuring the same thing correctly.
Switching definitions of MTTR mid-stream: Whether it's repair, recovery, or resolve, switching definitions breaks any trend line or benchmark comparison built on the data.
A CMMS is only as reliable as the definitions built into it. UpKeep's configurable fields let a team define operating hours, failure counts, and repair time consistently across sites so the numbers stay comparable as the program scales.
How to Improve MTBF and MTTR
These two metrics are driven by different parts of the maintenance process, so improving them requires different strategies. MTBF depends on what happens before a failure, while MTTR depends on everything that happens after one. Here's how to move each in the right direction.

Strengthen Preventive Maintenance to Boost MTBF
One-off fixes aren't enough to improve MTBF. A single repair might resolve a symptom but miss the underlying cause. That just sets up the next breakdown. Rather than reacting to each failure individually, build out a preventive maintenance (PM) schedule that targets the root causes of recurring issues, not just their symptoms.
In food and beverage manufacturing, for example, a conveyor motor that keeps failing every few weeks might point to a misalignment issue rather than a bad motor. Fixing the alignment, not just swapping motors, is what actually extends MTBF over the long run.
Keep a Well-Stocked Spare Parts Inventory to Cut MTTR
An underestimated but effective way to improve MTTR is maintaining a well-stocked spare parts inventory. A repair that should take an hour can stretch into days if a technician is waiting on a part that should've been on the shelf. This means tracking inventory levels against usage history for critical assets. That way, you can anticipate when you’ll need something before you run out of it.
Fleet maintenance teams see this play out often. Keeping common wear parts, like brake pads or filters, on hand can turn around a truck the same day instead of leaving it parked for a week waiting on a shipment.
Use Condition-Based Monitoring to Minimize Detection Time
Detection time is often the most hidden MTTR variable because it happens before anyone even opens a work order. Using condition-based sensors and monitoring tools to catch anomalies early can make that stage significantly shorter, cutting down on time before repair work even starts.
In a facility running rotating equipment, vibration sensors can flag a bearing trending toward failure days before it seizes. That early warning gives the team a head start instead of a surprise breakdown. It also shrinks the gap between when a problem starts and when someone actually notices.
Standardize Troubleshooting Procedures to Speed Up Diagnosis
Standardized troubleshooting procedures speed up diagnosis because teams can apply consistent methods when a technician who usually handles a piece of equipment isn't available. That uniformity enables new hires to ramp up faster by referencing a documented process.
A hospital facilities team offers a good example: With a regular troubleshooting checklist for HVAC issues, any qualified technician can step in during a night shift and follow the same diagnostic steps without delay.
UpKeep's mobile work orders give technicians instant access to an asset's repair history and documentation right on the floor, which cuts diagnosis time without adding head count. The goal here is to help the people in the trenches work smarter by putting the right information in their hands at the right moment.
The Bottom Line on MTBF and MTTR
MTBF and MTTR aren't interchangeable, and treating them that way can lead a team to fix the wrong problem. MTBF measures reliability, while MTTR measures maintainability. Both depend on accurate, consistently captured data and feed into the bigger picture of equipment availability.
Getting these numbers right isn't about chasing a perfect formula. It requires building the tracking habits and systems that make the inputs trustworthy in the first place. A CMMS that logs operating hours, repair time, and failure events automatically removes a lot of the guesswork that leads to inflated MTBF or inconsistent MTTR. From there, a team can fully trust what the numbers are telling them and act on it.
Ready to see how UpKeep can help your team track MTBF, MTTR, and availability without the manual spreadsheet work? Book a demo to see it in action.
Frequently Asked Questions About MTBF and MTTR
How do you calculate MTBF and MTTR?
MTBF is total operating time divided by the number of failures. MTTR is total repair time divided by the number of repairs. The key to both is accuracy in the inputs: MTBF should only count actual running time, and MTTR should reflect the full repair window your team has agreed to measure, from detection through verification.
What is the difference between MTBF and MTTR?
MTBF measures reliability, or how long equipment runs before it fails. MTTR measures maintainability, or how long it takes to fix it once it does. You want MTBF to go up over time and MTTR to go down. They rely on different data and point to different fixes when something's off.
How do MTBF and MTTR affect system availability?
Availability is calculated as MTBF divided by the sum of MTBF and MTTR. A higher MTBF or a lower MTTR raises availability, and vice versa. Teams can improve either metric to hit the same availability target, so the right approach depends on whether failures or repair speed are the bigger problem.
How much failure data do I need before MTBF is reliable?
MTBF calculated from just a few failures can swing wildly and mislead you. As a general rule, more failure events and more operating hours produce a more stable, trustworthy average. Many reliability practitioners look for at least a handful of failure cycles per asset before treating the MTBF number as dependable.
Want to keep reading?


Article
Asset Operations Management for Maintenance Teams


Article
Asset Operations Management for Reliability Teams


Article
Asset Operations Management for Operations Teams
4,000+ COMPANIES RELY ON ASSET OPERATIONS MANAGEMENT
Leading the Way to a Better Future for Maintenance and Reliability
Your asset and equipment data doesn't belong in a silo. UpKeep makes it simple to see where everything stands, all in one place. That means less guesswork and more time to focus on what matters.